Route Smarter. Build Faster. Scale Higher.

TamgaStudio is an AI Gateway that gives developers access to 1,000+ AI models through one OpenAI-compatible API. Route smarter with automatic provider failover, build faster with a single integration, and scale higher with semantic caching that reduces repeated token costs while keeping production applications available.

GPT-5 • Claude Opus 4.5 • Gemini 3.5 Pro • DeepSeek V4 Pro • Llama 4 • Mistral Large • Qwen 3 • GPT-4o • Claude Sonnet 4.6 • Gemini 3.1 Flash • o3 mini • Kimi K2.5 • Nemotron 3 Ultra • GLM-5 • GPT OSS 120B • GPT-5 • Claude Opus 4.5 • Gemini 3.5 Pro • DeepSeek V4 Pro • Llama 4 • Mistral Large • Qwen 3 • GPT-4o • Claude Sonnet 4.6 • Gemini 3.1 Flash • o3 mini • Kimi K2.5 • Nemotron 3 Ultra • GLM-5 • GPT OSS 120B •
OpenAI AI provider logo Anthropic AI provider logo Google Gemini AI provider logo Meta AI provider logo DeepSeek AI provider logo Mistral AI AI provider logo Qwen AI provider logo xAI AI provider logo NVIDIA AI provider logo Amazon AI provider logo Microsoft AI provider logo Cohere AI provider logo Kimi AI provider logo Together AI AI provider logo Alibaba AI provider logo ByteDance AI provider logo IBM AI provider logo Zhipu AI AI provider logo
TAMGA / AI INFRASTRUCTURE

TamgaStudio

A unified development layer that makes AI infrastructure simpler, more resilient, and easier to operate.

01

One API, a broad model ecosystem

TamgaStudio provides access to text, image, video, audio, and embedding models through one OpenAI-compatible API. Instead of maintaining a separate integration for every provider, teams use the same client, authentication flow, and shared model catalog. New models can be evaluated faster, while existing applications can move between options without being rewritten.
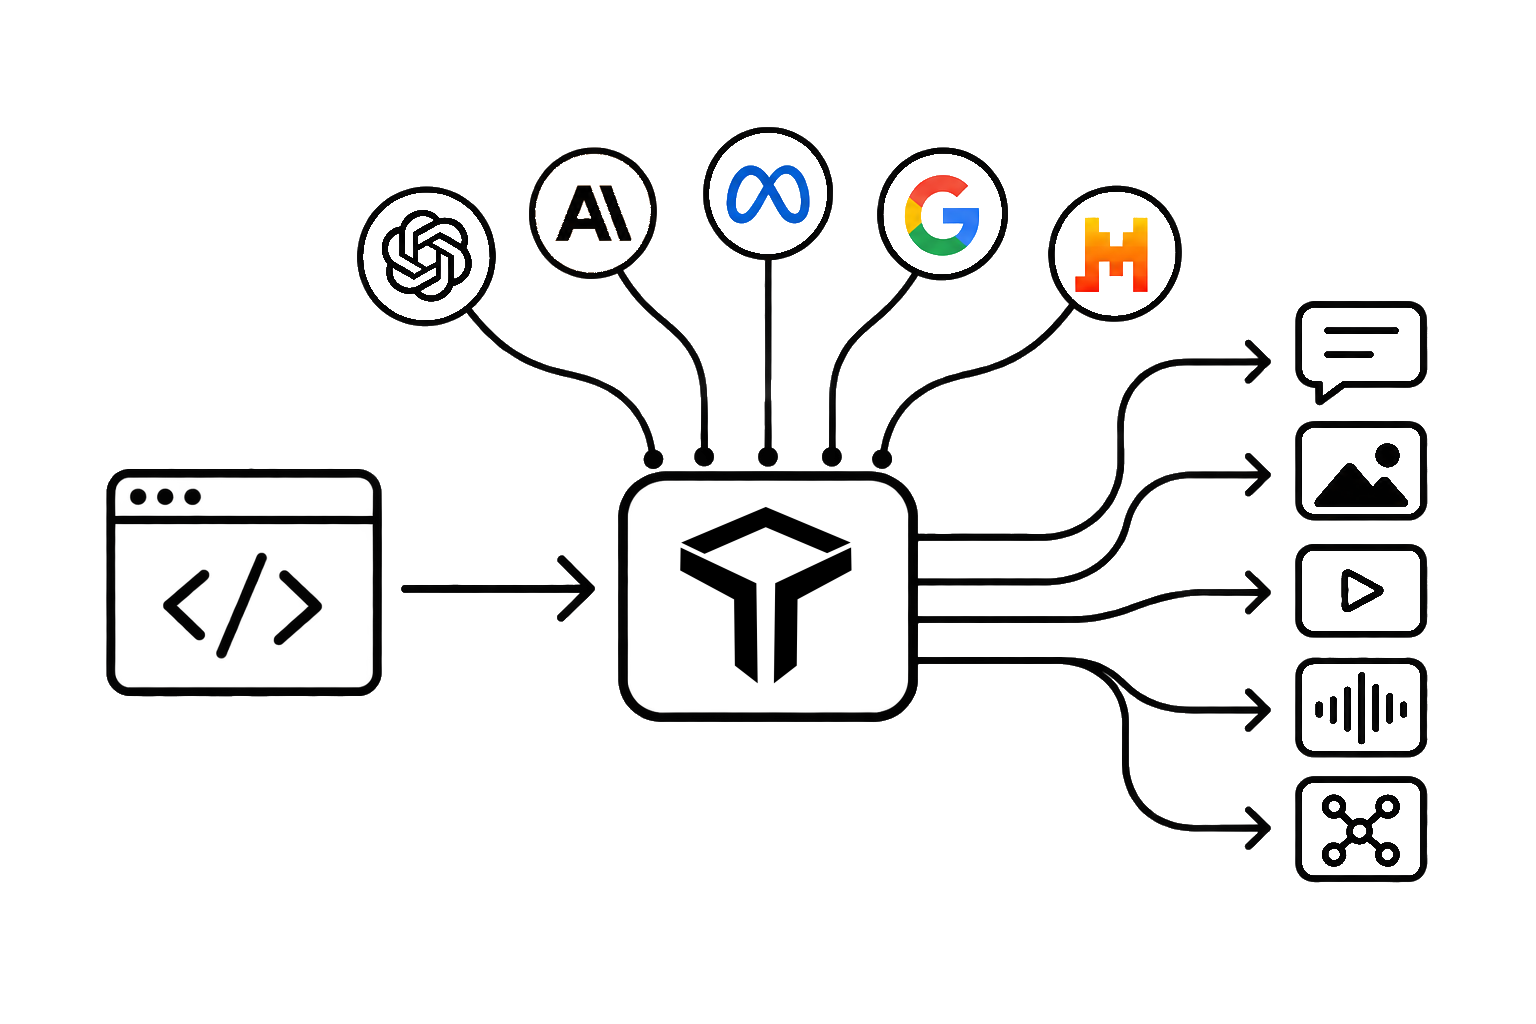
TamgaStudio unified AI model API diagram
02

Smart routing, resilient delivery

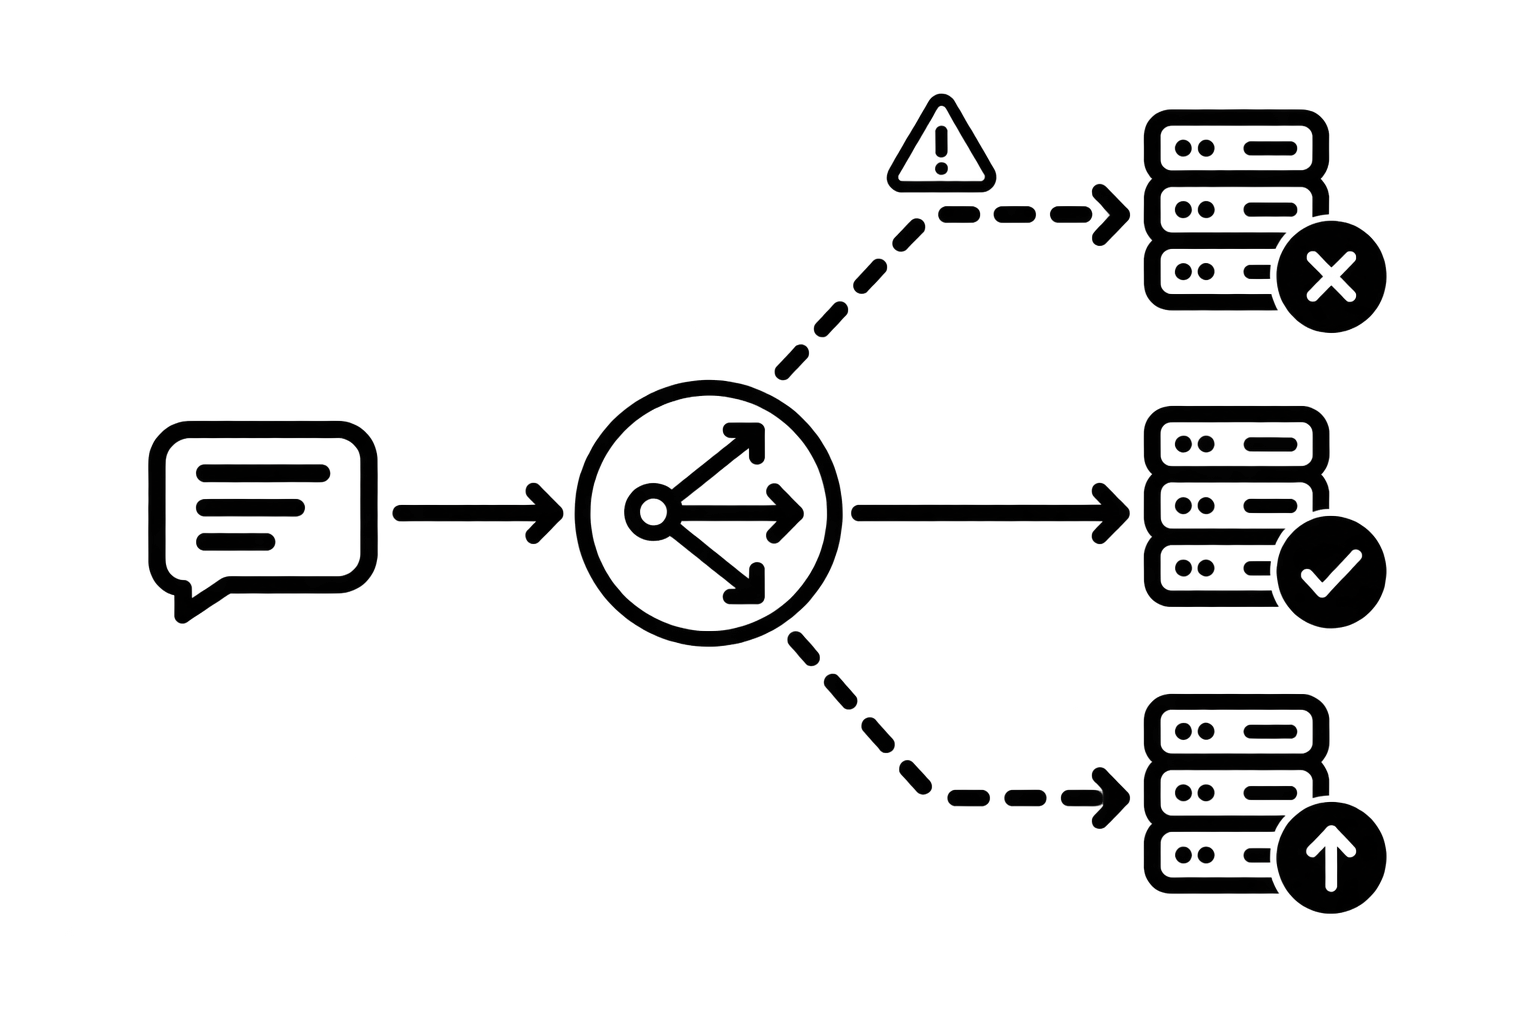
Each request is directed to an appropriate provider route through smart routing, using availability, cost, and routing priority. If one provider becomes unavailable, automatic failover moves the request to an alternative route. This reduces dependence on a single service and helps production AI applications remain available during traffic spikes, provider incidents, or temporary capacity constraints.

TamgaStudio smart routing and automatic failover diagram
03

Pay for useful work, not repetition

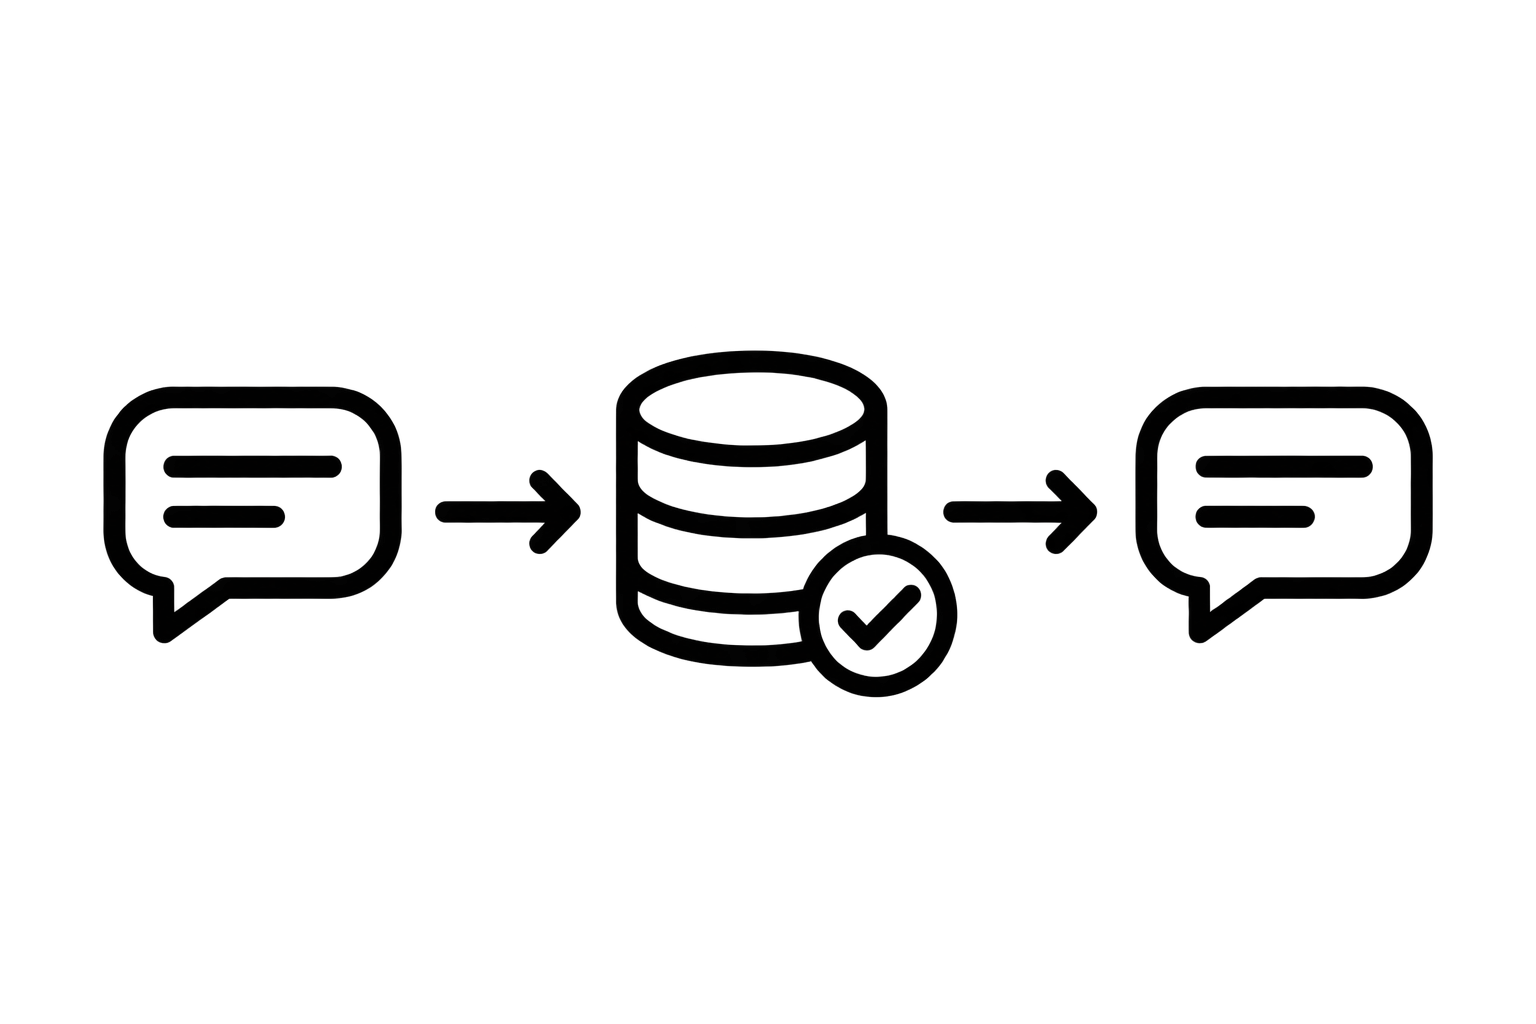
Tamga Semantic Cache detects semantically similar requests and safely reuses suitable responses that were generated before. Fewer unnecessary model calls mean lower latency and reduced repeated token costs. Model usage, pricing, and route information remain visible from one dashboard, allowing developers to focus on the product experience instead of managing infrastructure details.

Tamga Semantic Cache cost and latency diagram

Tamga Semantic Cache

What is Semantic Cache?

1338+

AI Models

429.7K

Tokens Processed

%50

Cache Savings

Get Started in 3 Steps

From account to first API call in under 5 minutes.

1

Create Account

Sign up for free and grab your API key from the dashboard.

2

Change Base URL

Change one line in your existing OpenAI code: base_url = https://api.tamga.studio/v1

3

Pick a Model & Run

Choose from 1000+ models. Failover and cache activate automatically.

API

One endpoint. Every model.

Ready to Simplify Your AI Infrastructure?

Integrate in 5 minutes, reduce costs, and run AI without interruptions.